I sat down this week to write the fourth piece, the one about the crew.
I could not do it.
Something Dave Iberson-Hurst wrote Thoughts from Milan which got under my skin and stayed there all week. The longer I sat with it, the clearer it became that I had not actually finished the third piece. I described the car the passenger deserves and left out the part that decides whether the car ever moves. So this is not piece four. This is article three, part two.
Go back to the passenger. They are still on the track. Last week I told you about the car, and what it represents, the foundation for clinical trials. What I did not tell you is that a foundation is only as useful as the points where the next thing connects to it. Pour it into a shape that only one crane can lift, and the next trial in the same disease still starts from bare ground. The protocol I promised would travel does not travel. The library does not open, because the books are written in a private script.
That is the part that was bothering me all week. Let me show you where it comes from. I apologize ahead of time if I get too technical in this article, but this needs to be said.
Feel free to copy paste into your favorite AI and ask "what in the hell is this author talking about?".
Dave is the USDM Product Owner. He has called USDM the foundation twice this spring, in an April newsletter and again in his note from Milan, and he is right to. The model is real. The build is shipping. None of that is in question, and nothing here is an argument against it.
What Dave did in Milan was name the destination. He asked for linked data. He made the point that you can only talk to data that is connected to its meaning, a wish people in this industry keep expressing and keep not getting. And he said the thing I keep coming back to: "mapping exists because we cut the relationships in the first place." Leave the scissors at home, he wrote. Stop severing the relationships at the source and you stop needing armies of people to stitch them back later.
He was not alone in that room, or under that post. The Chris Decker (CEO of CDISC) replied that he has spent twenty years arguing that we lose the context at the moment of collection and then spend the rest of the trial gluing Humpty Dumpty back together. A contributor who helps build the standards said the newest version of SDTM is still locked in table thinking, where everything is a row and a column. An advisor from one of the large platform vendors said you cannot trust an AI sitting on top of this data without harmonized meaning underneath it.
None of them coordinated. They converged. That is the same thing I said five names ago in the last piece. It just happened again, in public, in a single comment thread, inside of a week.
So here is my problem with my own optimism.
Everyone in that thread is asking for the same thing. Relationships. Context. Meaning that survives the trip. The foundation we are pouring does not deliver it yet, for a reason that is easy to walk straight past.
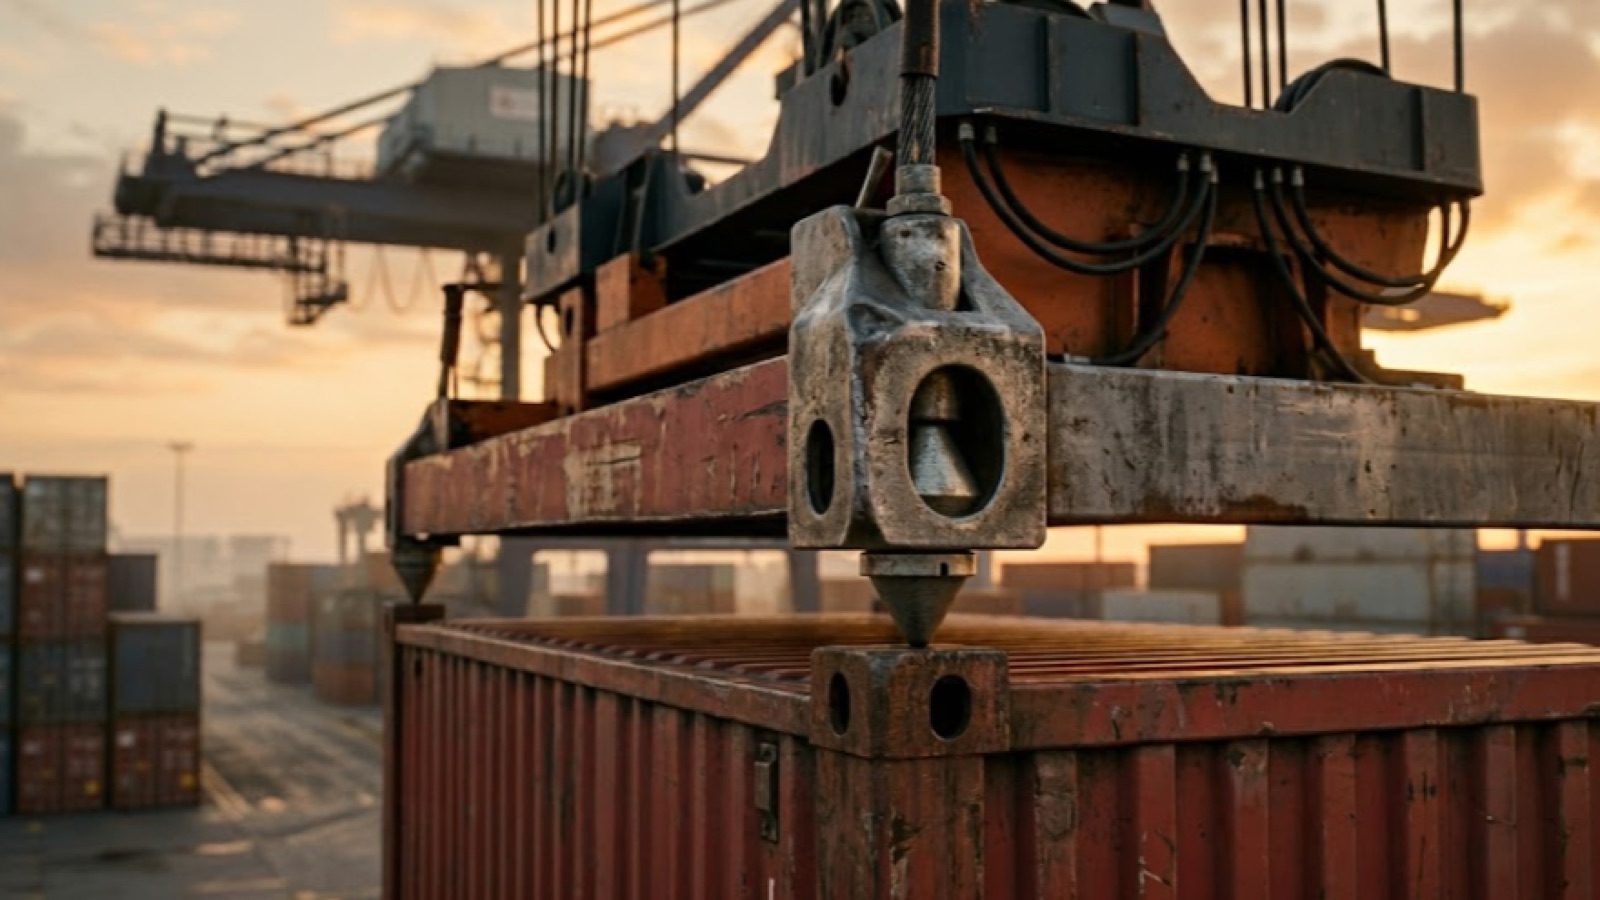
Bill Illis gave us the right image last year. Agree on a container, the way the world agreed on shipping containers and electrical outlets, and things start to move. He is right. But a shipping container does not travel because it is a box. It travels because its corner castings are machined to the same dimensions everywhere, so every crane in every port on earth grabs it the same way. The box is the easy part. The connection points are the hard part.
USDM gives us the box. It is a genuine, shared model of what a protocol is. What is not standardized yet is the connection points. The identifiers.
Watch where USDM actually runs. Every demonstration of it I have seen runs on a Neo4j property graph. Dave's own walkthrough stores it that way. OpenStudyBuilder stores it that way. What it does not give you by default is a globally resolvable identifier, one that still means the same thing outside the store that created it. You can add one by hand. Nothing in the model makes you, so almost nobody does, and identity stays local. RDF makes global identity the default instead of the exception.
Open a single Biomedical Concept and you see it in plain sight. The code is a bare string, C49677, and the system it belongs to is named in the field beside it, not carried inside the identifier. The mapping to LOINC is another bare string next to another field that spells out the system. The link points to a human browsable page, not an identifier a machine resolves. Lift the string out of that file and nothing about it resolves on its own.
So we built the container, and then we filed the corner castings by hand to fit one crane. It looks like a shipping container. It cannot be lifted in the next port.
This is not a USDM problem. It is the same failure four standards deep, and once you see it you cannot unsee it.
FHIR was built to move data between systems. Grahame Grieve, who designed it, has said for years that it was made for exchange and not for storage. The industry stored it anyway, then bolted on whole new specifications to query and warehouse it, because the thing was never shaped to sit still. SDTM is a submission format that the field treats as the data model, which is why a CDISC contributor can stand up in 2026 and say the newest version is still rows and columns. BRIDG was an ambitious model of the whole domain that froze in 2019 and was formalized into an ISO standard without ever becoming something you could run. And USDM, the newest and the best of them, is being poured into a property graph whose identifiers do not resolve.
Different decade, different standard, same vector. In every case the meaning is encoded as a value sitting inside a chosen container. A cell in a table. A column in a transport file. A node in a property graph. When the meaning lives inside the container, it cannot leave the container.
Notice what this is not. It is not only vendors locking you in, although they do that too. USDM is open. OpenStudyBuilder is open source. Nobody is screwing anybody here, and the data still cannot travel. That is the harder truth, and it is the one worth sitting with. Open is necessary and it is not sufficient. A foundation can be completely open and still trap everything built on it, if its identifiers only mean something in one place.
There is a clock on this now, and it is the reason I could not let the third piece stand as written. Dave's blunt point in Milan was that the useful kind of AI runs on clean, well modeled data, and clean, well modeled data is the one thing this industry has spent two decades failing to produce. A foundation whose identifiers do not resolve cannot feed that. We would be handing the most powerful tool we have ever had a pile of notebooks it cannot read.
Here is what it costs the passenger, in the terms I used last week.
I promised you the protocol would become a library. That the next sponsor running a trial in the same indication could read a previous protocol as data, fork it, and start faster. That promise is real, and it is conditional. A library only works if anyone can read the books. Encode the protocol in a graph whose identifiers resolve in one system, and you have not written a library. You have written one more private notebook, in one more private script, that the next team has to transcribe by hand. Which is the same interpretation tax I described last week, moved up one floor and given a more modern name.
The passenger does not get the months back. They wait the same wait, while we admire a foundation the next trial cannot actually build on.
So what has to be true, beyond what I already said.
The corner castings have to be standard. The identifiers in the foundation have to resolve the same way everywhere, for every system, the way a web link resolves no matter whose browser opens it. That is what linked data means when it is done properly, and it is exactly what Dave is asking for when he asks to leave the scissors at home. A property graph full of local strings is not that. Real linked data is.
The reference implementations have to share more than a model. They have to share resolvable identity. Two systems can both implement USDM perfectly and still exchange nothing, if each one mints its own local identifiers. Same model, different castings, no lift. The thing that must be common is the identity layer, not only the schema.
And the proof already exists. I showed you last week that other industries run exactly this, a cross-domain graph with resolvable identity, at city scale and at national scale. The question was never whether it works. The question is whether clinical research will pour its foundation with castings the next crane can lift, or pour it one more time to fit a single port.
Back to the passenger. They are still on the track. The foundation is still being poured, and that is still good news. I only want it poured once, and poured right, so that the trial after theirs does not begin again on bare ground.
Now I can write the fourth piece, the one I failed to write this week. Because a crew that has done this before only helps the passenger if the car they pick up is the same car, with the same parts, that connect the same way every time.
In clinical trials, patients deserve a crew that has done this before. That is next.
About the author
Bo Lora spent four years at AWS deeply embedded across more than thirty roles in the clinical research value chain, from sites to sponsors, CROs, tech vendors, start-ups, and regulators. He held Core Technical Field Community Leadership in Health and Life Sciences. Before that he was a consultant at BearingPoint, working across finance, telecommunications, manufacturing, and semiconductors. He started his career as a BBN Field Engineer in Stuttgart in 1989, where he once flew to Oslo to fix a modem that was unplugged.
He is active in CDISC, Vulcan, and TransCelerate, and serves as AI Faculty for ValueAdd Group.